MOSS-Image

MOSS-Image is an open-source text-to-image model from the OpenMOSS team, released on October 16, 2026 under the Apache-2.0 license. Its 5B diffusion transformer is built for images where the words matter: posters, menus, infographics and signs with long English or Chinese text, plus a JSON layout mode that places each element where you want it. GoEnhance does not offer MOSS-Image yet. The creation console below uses GoEnhance 2.0 Lite, our own lightweight image model, which also handles text in images and is free to try.
Retro Travel Poster
Retro Travel Poster
Retro Travel Poster
Bilingual Chalkboard Menu
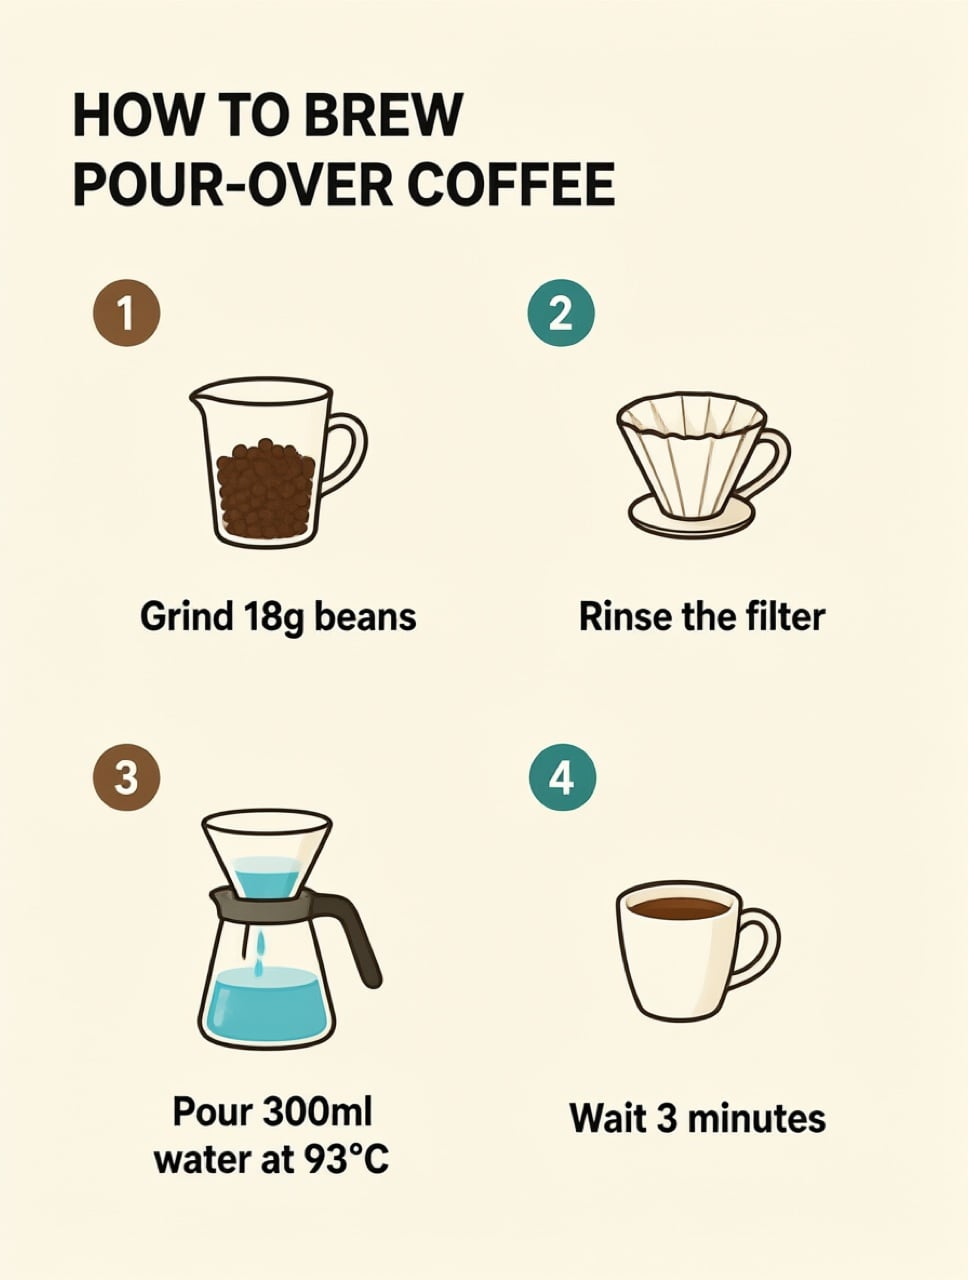
Step-by-Step Infographic
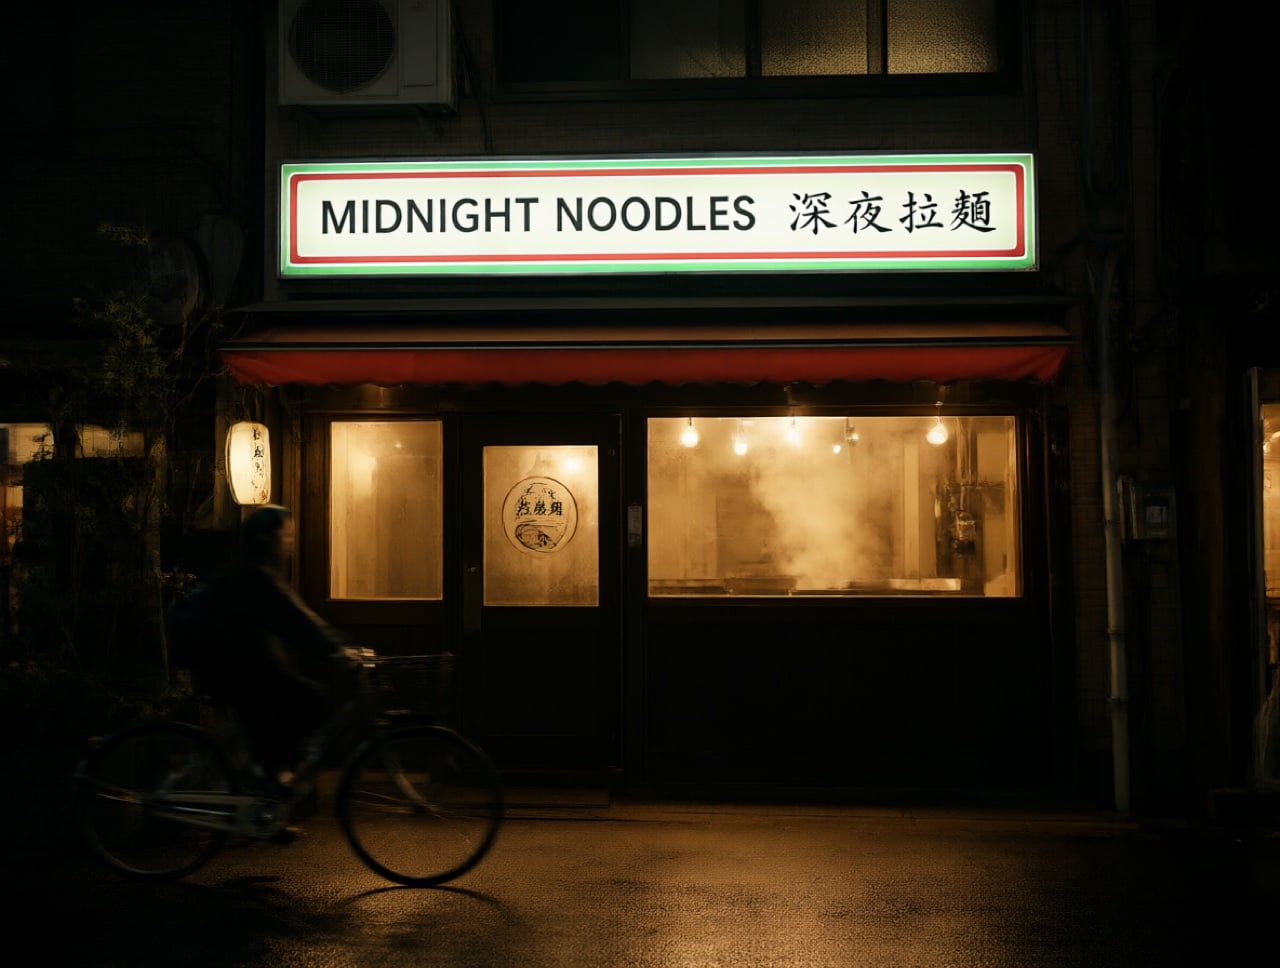
Neon Restaurant Sign
GoEnhance 2.0 Lite
Prompt
Example prompts
Opens the GoEnhance editor with this model and prompt ready.

What MOSS-Image Is Good At

Long, accurate text rendering

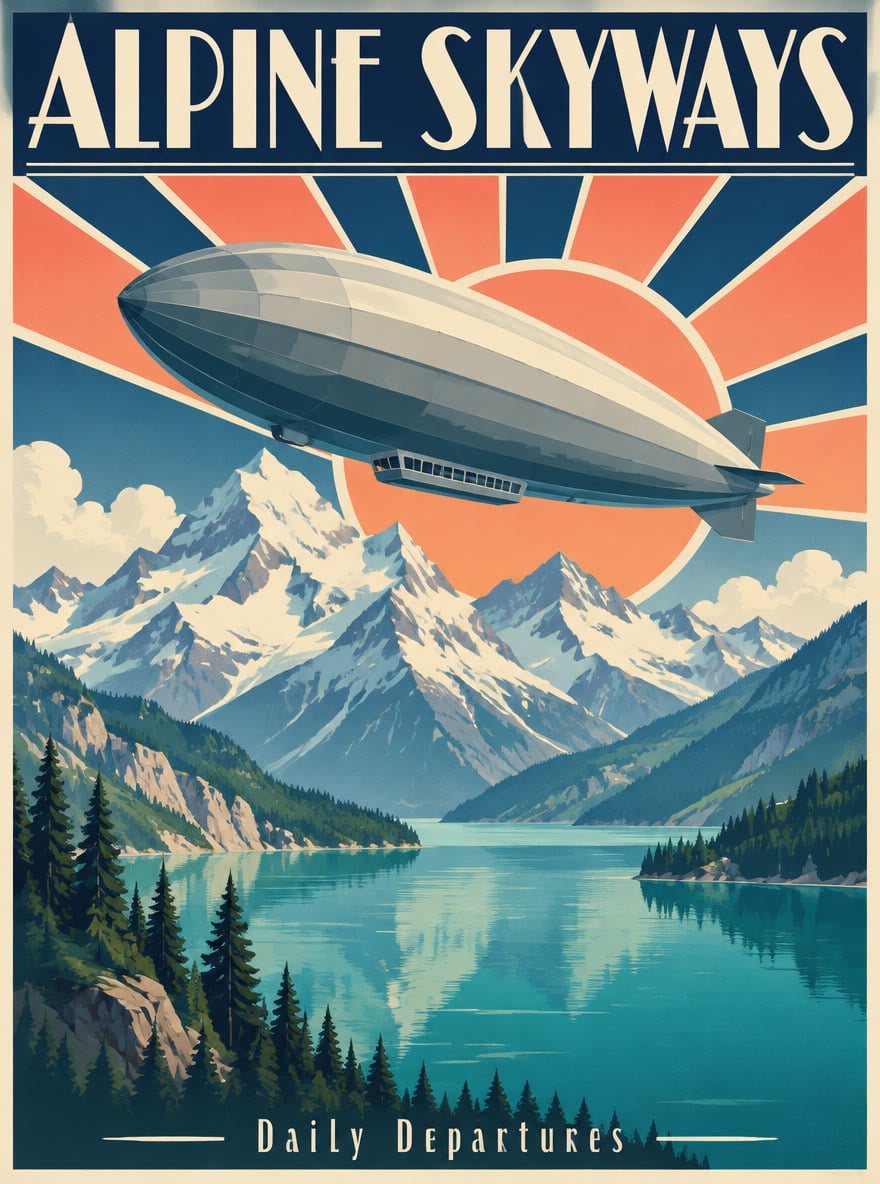
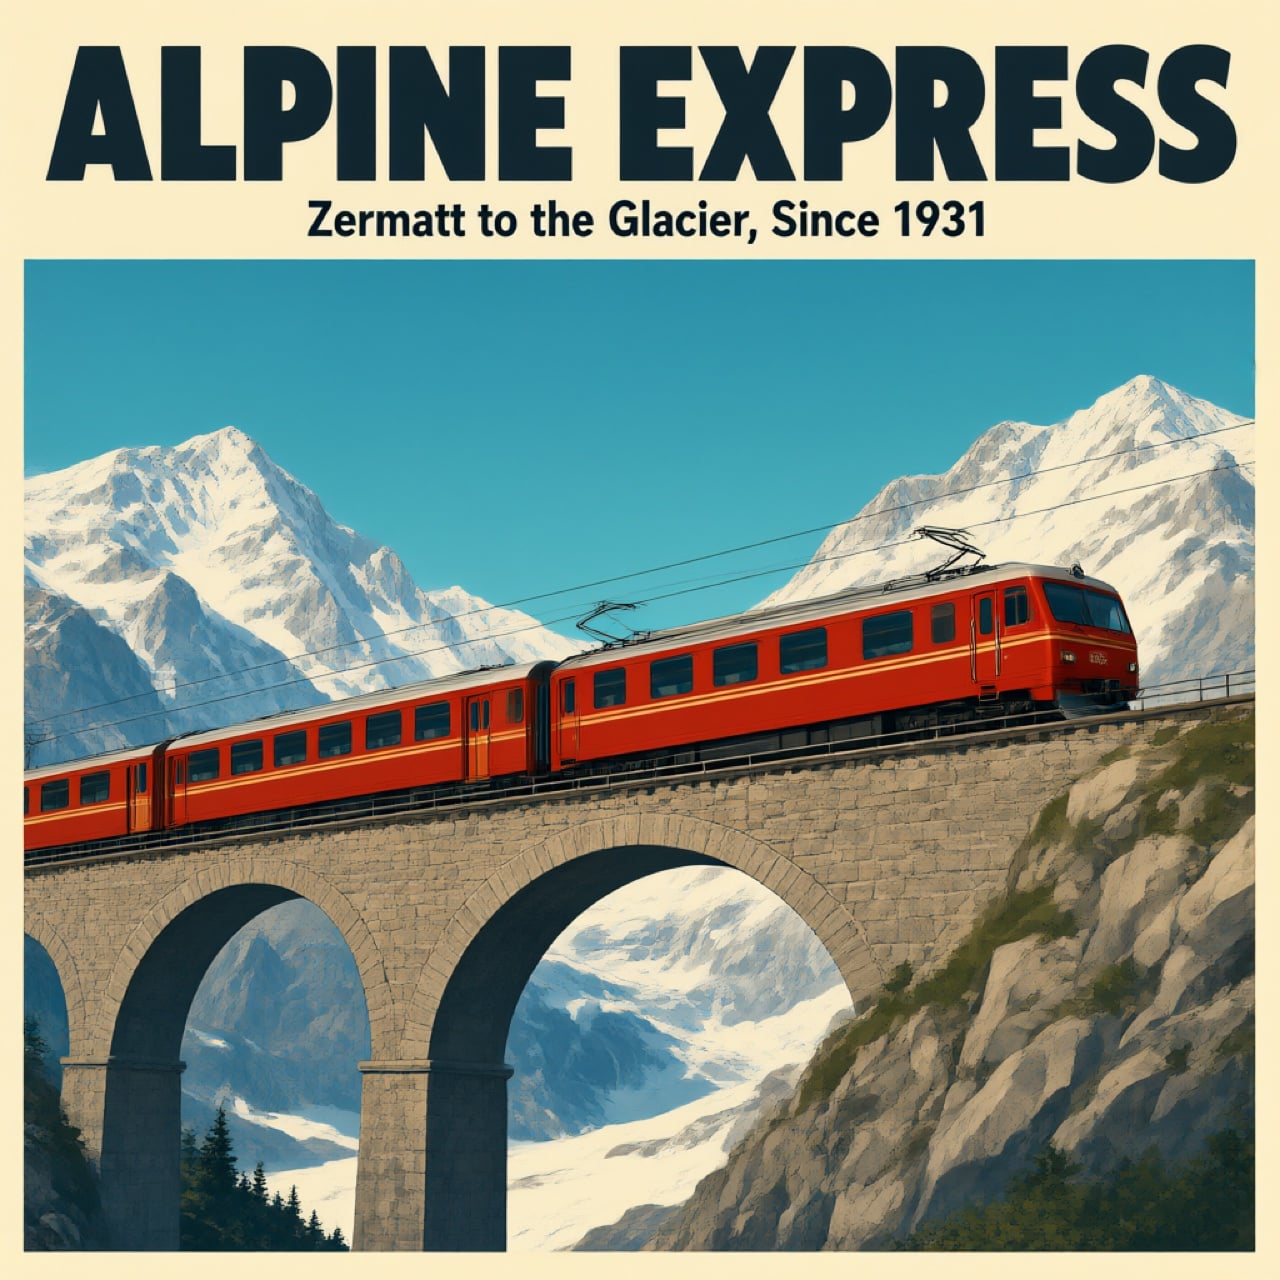
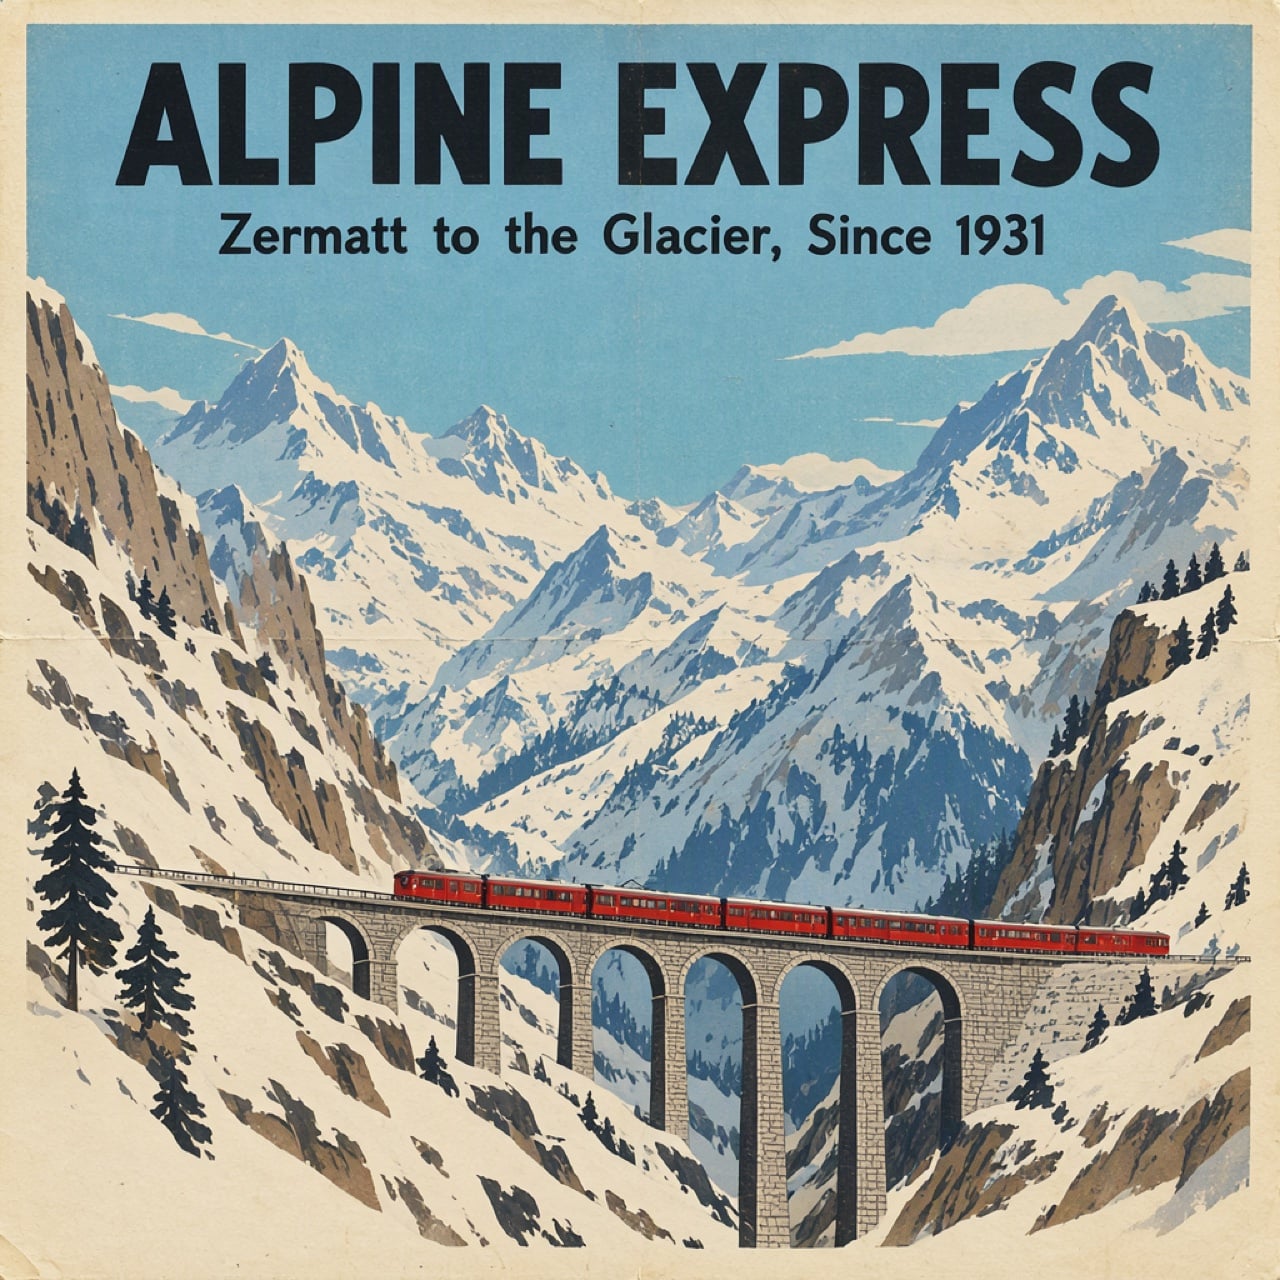
MOSS-Image is trained to spell headlines, slogans and small print correctly. In OpenMOSS's technical report it averages 96.3 on the LLTB long-text benchmark. This travel poster was made with MOSS-Image on the official demo: the headline and subline came out exactly as written.
Text that comes out right

English and Chinese side by side

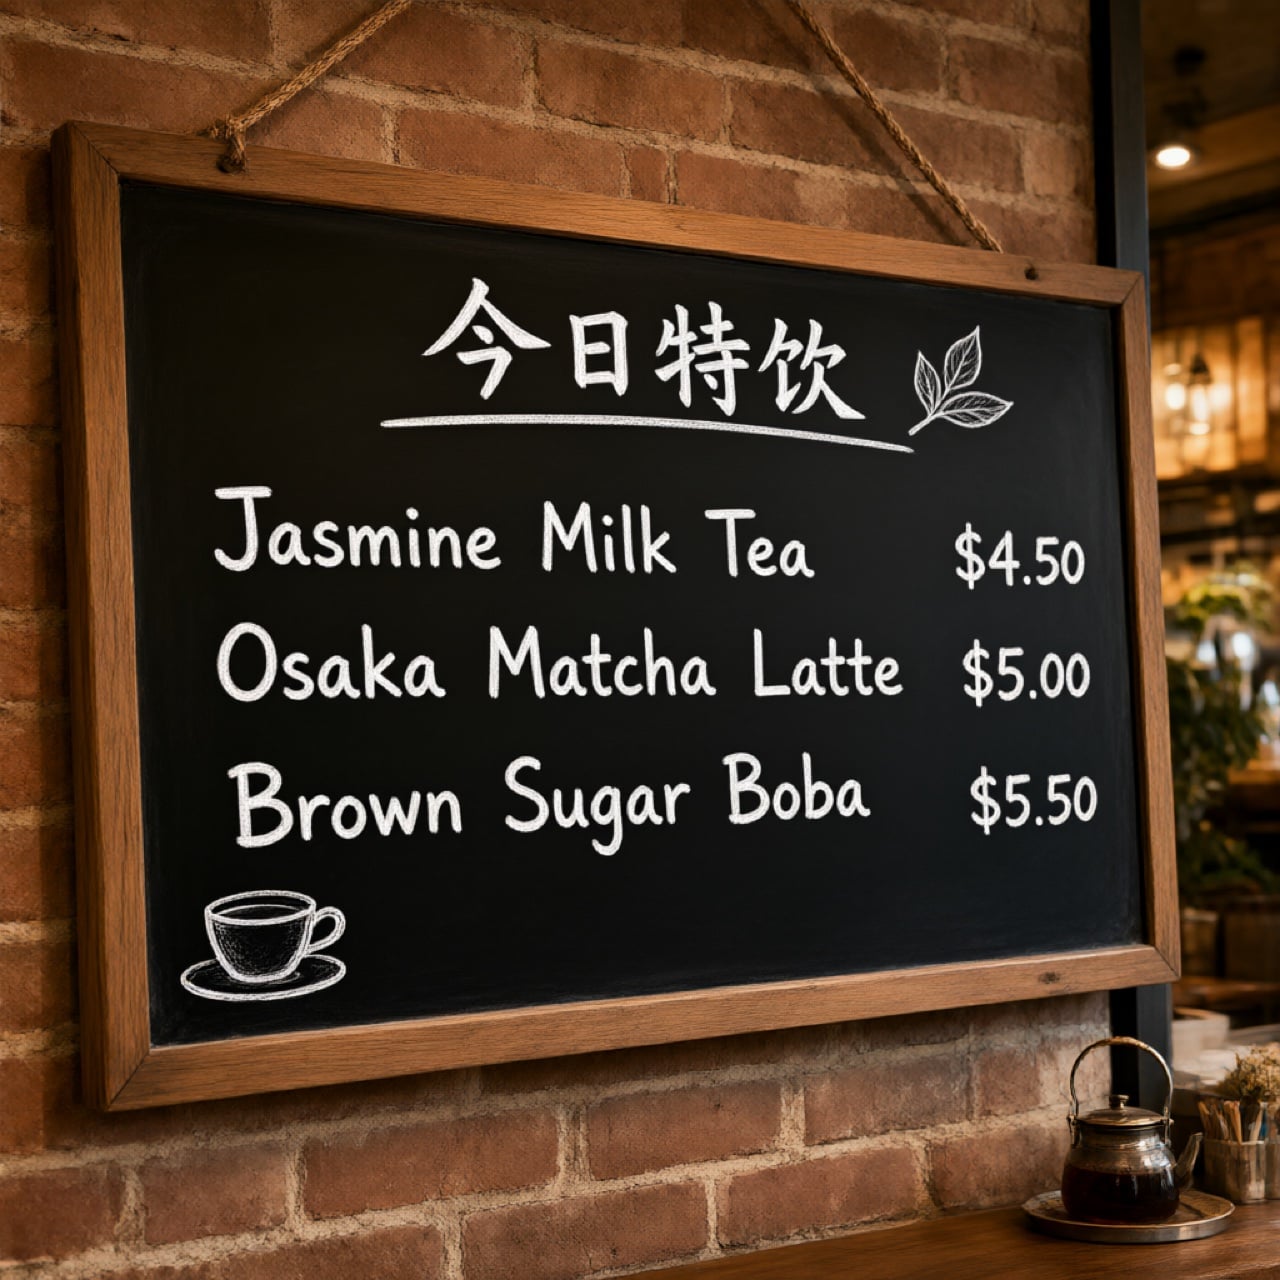
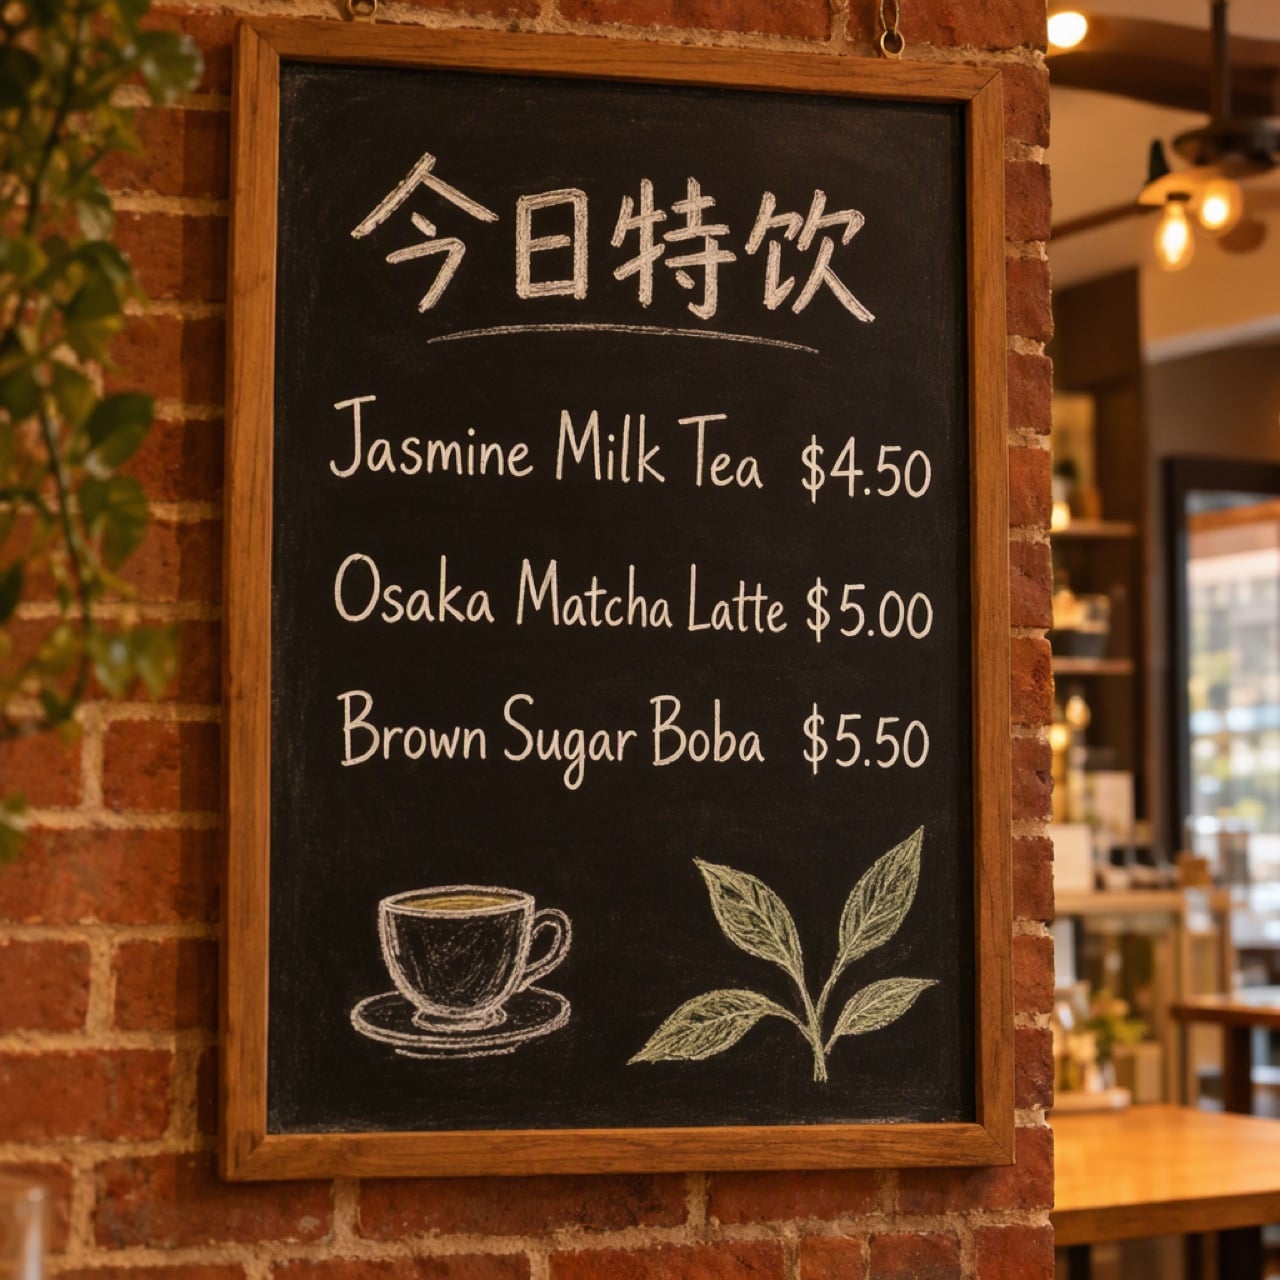
The model renders both English and Chinese, including handwritten-style lettering, in the same picture. This chalkboard menu, with a Chinese title and English prices, was also generated with MOSS-Image on the official demo.

English and Chinese in one image

Put every element where you want it

Besides normal prompts, MOSS-Image reads a JSON layout prompt: list each object or text block with a bounding box and it keeps them in place. Prompts can run up to 4K tokens, which suits dense posters and infographics. The infographic shown here is an illustration made with GoEnhance 2.0 Lite, not a MOSS-Image output.

Layout control

Open weights you can run yourself

Weights for MOSS-Image-Base and MOSS-Image-SFT are on Hugging Face and ModelScope under Apache-2.0, with ComfyUI support from day one. It needs an NVIDIA GPU and recommends 50 steps, CFG 3 and 1 to 2 megapixel images. The neon sign shown here is an illustration made with GoEnhance 2.0 Lite.

Open weights

MOSS-Image-Base vs MOSS-Image-SFT

FeatureMOSS-Image-BaseMOSS-Image-SFT
What it isPre-training checkpoint with the full training signalFine-tuned from Base on curated data
Best forLoRA training and fine-tuningEveryday text-to-image and layout prompts
Size5B parameters5B parameters
LicenseApache-2.0Apache-2.0
Image editingNo (text to image only)No (text to image only)
Available on GoEnhanceNot yetNot yet

How to Create Text-Heavy Images on GoEnhance Today

01

Write the scene and the words

Describe the subject, style and layout in the console above, and put every word you want in the image inside quotes.

02

Generate with GoEnhance 2.0 Lite

Click generate to open the GoEnhance text-to-image studio with GoEnhance 2.0 Lite selected. It costs 6 tokens per image at 1K and 12 at 2K, and the free plan can use it.

03

Fix and edit

Switch to image to image to change words, colors or objects with an instruction, using up to 5 reference images.

04

Come back for MOSS-Image

We will add MOSS-Image to this page when it becomes available on GoEnhance.

Frequently Asked Questions

You may want to know

What is MOSS-Image?

MOSS-Image is an open-source text-to-image model family from the OpenMOSS team. It uses a 5B single-stream diffusion transformer with a 9B language-model text encoder and focuses on accurate text rendering and layout control.

When was MOSS-Image released?

OpenMOSS released MOSS-Image on October 16, 2026, with code, weights, a technical report and a live demo on Hugging Face Spaces.

Is MOSS-Image free for commercial use?

The model weights are released under the Apache-2.0 license, which allows commercial use. The pipeline code and third-party components keep their own licenses, so check those before shipping a product.

Can MOSS-Image edit images?

No. The current model is text to image only: it does not take reference images or edit an existing picture. OpenMOSS lists image-conditioned generation as future work. To edit a picture today, use GoEnhance 2.0 Lite in image to image mode.

What is the difference between Base and SFT?

MOSS-Image-Base is the pre-training checkpoint, meant for LoRA training and fine-tuning. MOSS-Image-SFT is fine-tuned from Base on curated data and is the one to use for everyday text-to-image and layout prompts.

What languages can it write in images?

MOSS-Image renders English and Chinese text, including long passages and handwritten-style lettering.

How do I run MOSS-Image locally?

Download the weights from Hugging Face or ModelScope and use the official code, ComfyUI or vLLM-Omni on an NVIDIA GPU. OpenMOSS recommends 50 steps, CFG 3, shift 5 and images of 1 to 2 megapixels (0.25 to 4 megapixels are supported, in multiples of 16).

Can I use MOSS-Image on GoEnhance?

Not yet. The console on this page uses GoEnhance 2.0 Lite, our own lightweight image model. It costs 6 tokens per image at 1K and 12 at 2K, works on the free plan and edits with up to 5 reference images. The two MOSS-Image examples on this page were made on OpenMOSS's official demo; the console examples were made with GoEnhance 2.0 Lite.

Start Creating on GoEnhance Today

MOSS-Image is not available on GoEnhance yet, but GoEnhance 2.0 Lite is ready now in our text-to-image studio: 6 tokens per image, free plan included.

Try GoEnhance 2.0 Lite